Which Claude model for marketing? It depends on the task, not on which is newest. Use the most capable model for complex audits, long agent sessions and multi-rule skill files. Use a cheaper model for routine drafts and simple rewrites where output quality is the same.
Every time a new model is announced, social feeds fill with claims that it is better at everything. In my experience that is not true. When I compared two Claude versions on real marketing workflows, with the same skill files, the same connections and the same client data, some tasks improved and some got no better or even worse for the price. So which Claude model for marketing is right? It depends on the task, and the only reliable way to know is to test.
Where the stronger model earned its keep
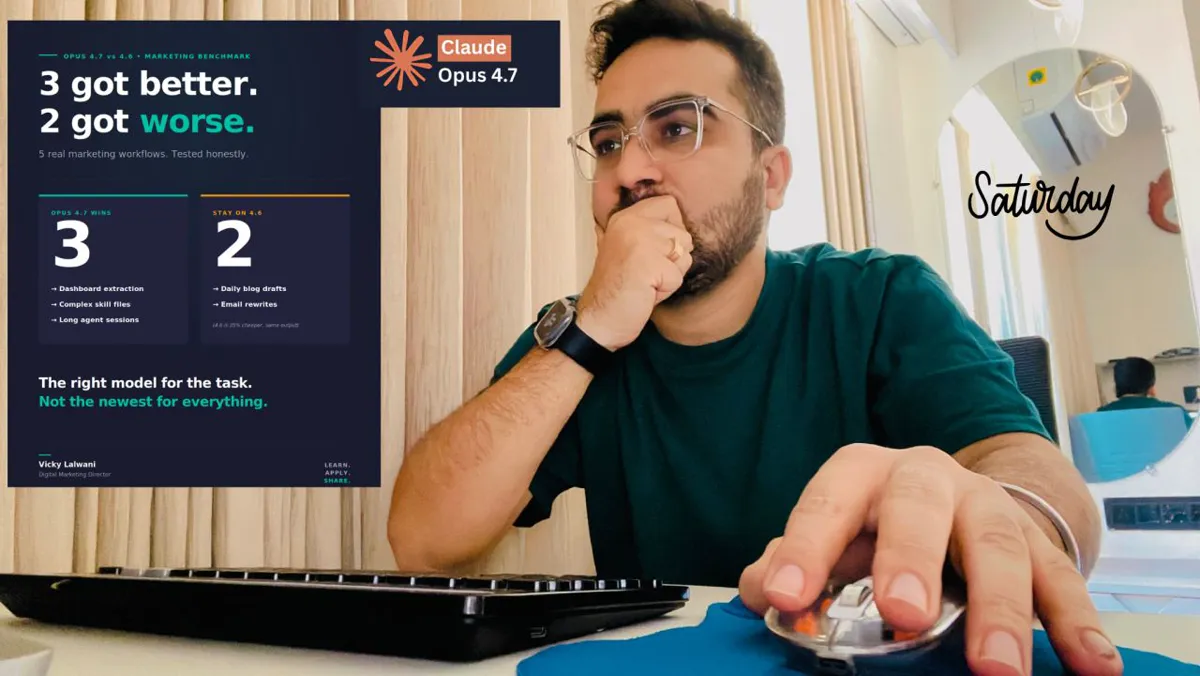
Three kinds of work clearly benefited from the more capable model. I describe them in general terms because specifics change with each release, and you should check the vendor's current documentation.
- Extracting data from screenshots. When I uploaded a full search performance screenshot, the stronger model read the whole table, including keywords, click rates and positions, without needing cropping or follow-up prompts. The older model missed rows on the same image.
- Skill files with many rules. My SEO audit skill has a long list of rules. The stronger model followed all of them. The older one skipped a few each run, which is the kind of quiet error that damages an audit.
- Long agent sessions. In a multi-hour competitor research sprint, the stronger model kept hold of the original brief through the whole session. The older one needed to be reminded periodically.
Where I stayed on the cheaper model
Two workflows did not justify the upgrade.
- Routine blog drafts. The output was effectively identical, and the older model was cheaper to run.
- Simple email rewrites. Extra thinking just used more tokens for no visible gain in quality.
The lesson is boring but important: the right model for the task, not the newest model for everything.
A simple rule for choosing a model
I use a rule of thumb that you can adapt. Ask three questions about the task:
- Does it involve many rules or constraints that must all be followed?
- Does it run for a long time or depend on holding a brief across many steps?
- Does it need reading dense visual data, such as dashboards and screenshots?
If the answer to any of these is yes, use the stronger model. If all three are no, start with the cheaper one and only move up if the output disappoints. Think of it like staffing: you would not send your most senior strategist to reformat an email.
How to run your own comparison
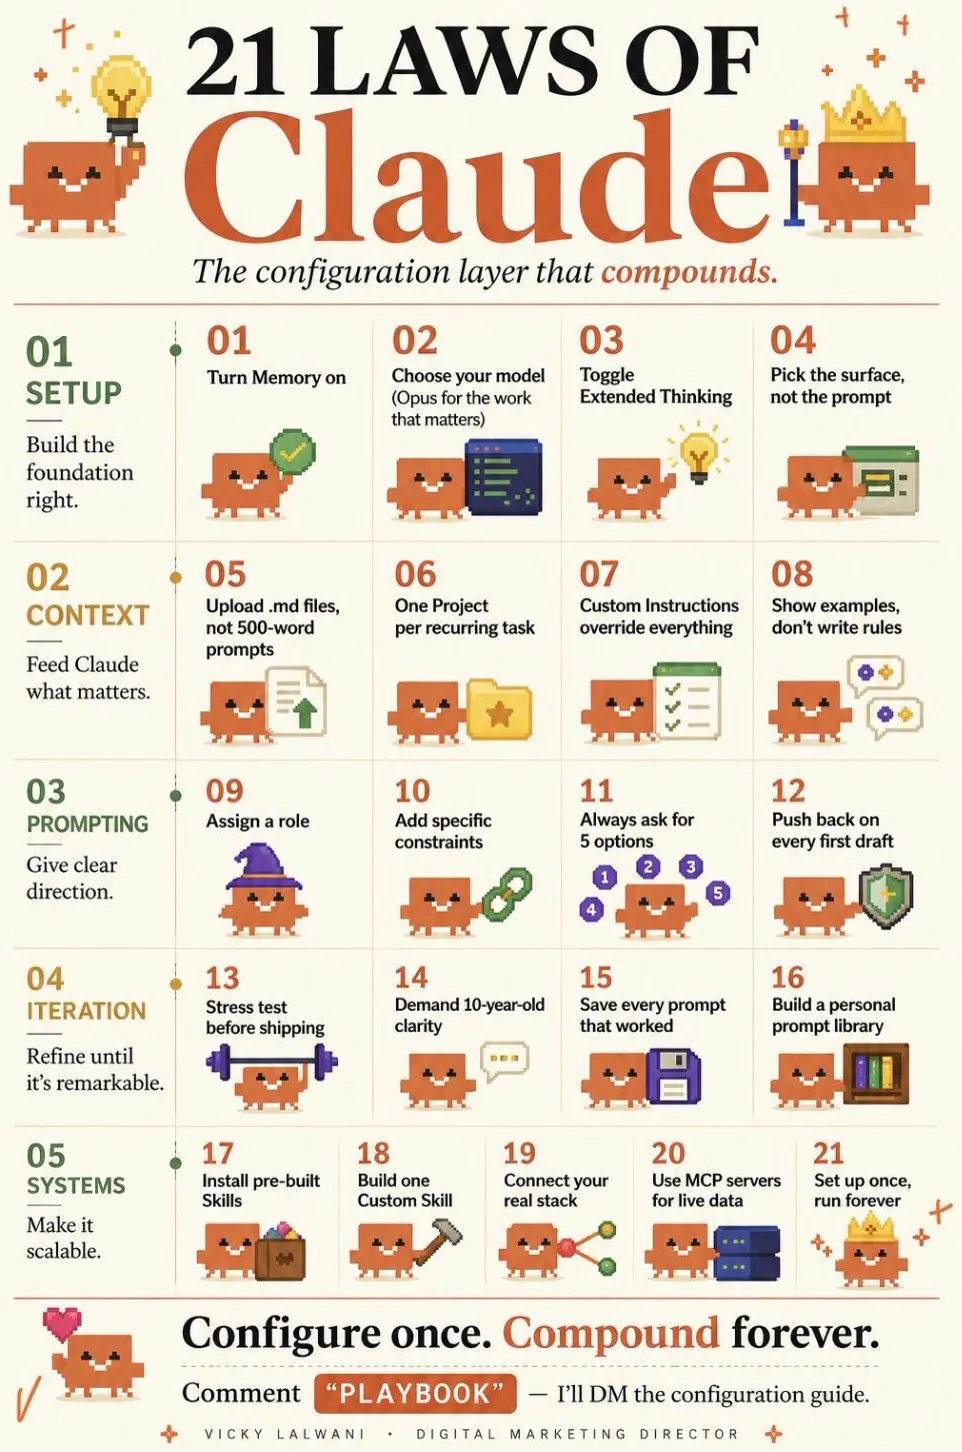
You do not need a lab. Pick five workflows you do every week and write a one-line quality check for each, such as "follows every rule in the skill" or "no missing rows in the table". Run each on both models using identical inputs. Record quality and rough cost. Then decide task by task, and write the decision into the instructions of each skill or project so everyone on the team uses the same default.
Repeat the test whenever a major release arrives. Results shift, and what was true last quarter may not be true next quarter. Because of that, I avoid hard-coding a model name into anything I plan to keep for years.
Why this matters for 2027 budgets
If your team uses Claude heavily, model choice becomes a real line in the budget. Matching the model to the task keeps quality where it matters and spend under control. It also separates a marketer who uses Claude from one who runs a system. If you want help setting these defaults for your team, my Claude consultant service covers it, and my free guides explain the basics of skills and projects.
Which Claude model for marketing agencies and in-house teams
Agencies running many accounts care about cost per task, while in-house teams usually care about consistency. Either way, document the default model for each skill so nobody guesses, and allow an override for hard cases. Review the defaults after each major release, because a task that needed the strongest model last quarter may run fine on a cheaper one now, and the reverse can also happen.
This article expands on my post on LinkedIn ↗.
FAQ
Should I always use the newest Claude model?
No. Newer models can be better at complex, long or multi-rule tasks, but for simple writing the output may be the same at a higher cost. Test on your own workflows.
How do I compare two models fairly?
Use the same skill files, the same connections and the same client data. Run each task on both models and judge the output against a short checklist.
Does extended or adaptive thinking always help?
No. It helps on audits and reasoning-heavy tasks. On short rewrites it can use extra tokens without improving the result. Check the vendor's current docs for how it works.